Melbourne, Australia
Read · Test · Keep
My AI said the abstract cut off. It was right.
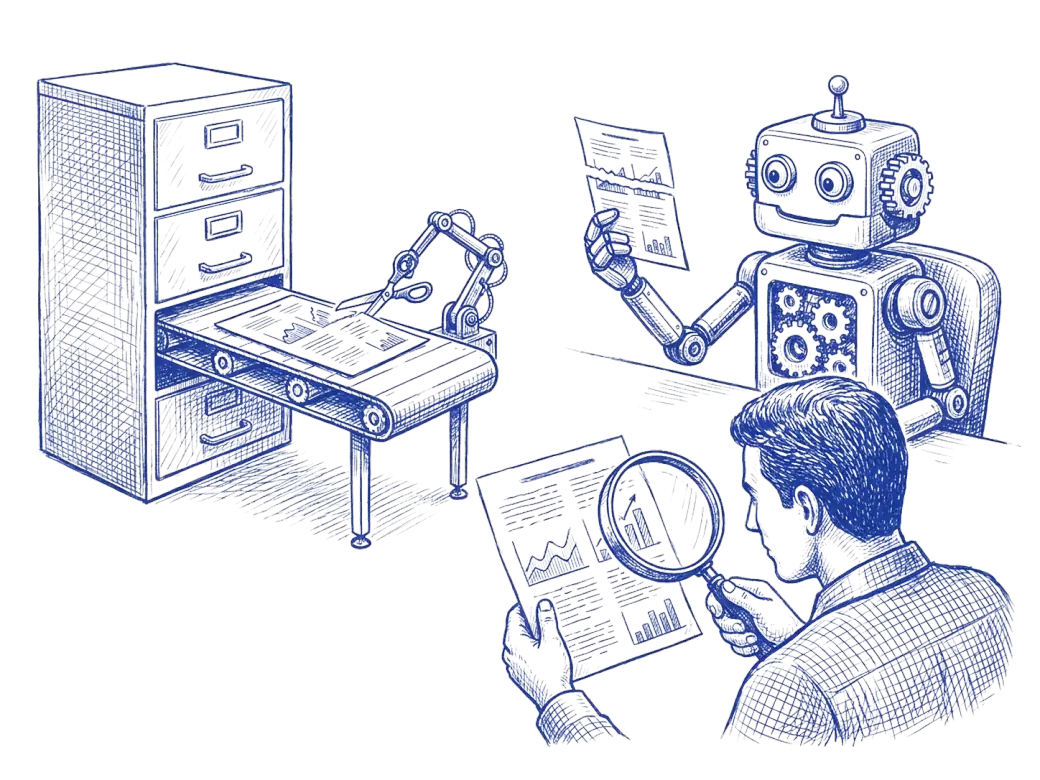
An LLM is only part of how an answer gets back to you. There’s code before it, deciding what it reads, and code after it, deciding what you see.
One entry from my AI Signal Digest this morning:
The abstract cuts off mid-word at 'leading to incomplete s', so I cannot tell what results, numbers, or baselines the paper reports.
It wasn't the only one. Every one of the 87 research papers in that digest said something like it.
The obvious reading is that the model is the weak link. It reads research papers for me, and today it couldn't get through a paragraph. Swap it for a better one.
The paper's full abstract was sitting in my own database the whole time, all 1,183 characters of it. The sentence carries on: "leading to incomplete scope, weak taxonomies, and unreliable citations." The model never saw that part. Something in my pipeline cut the text at character 500 before handing it over, and the model reported what it had been given.
An AI assistant found it while helping me write up what I'd spent that day learning. Which was this exact mistake, made by me, over and over.
An answer is a relay
The way I'd put it now is that an LLM is only part of how an answer gets back to you. There's code before it, deciding what it reads, and code after it, deciding what you see. When the answer is wrong, you can't point your finger at the model until you've looked at the rest.
I learned that from a tutor. LearnHarness is an open-source app that tests what you already know, maps what you don't, and teaches one step at a time with a check question after each. I loaded it with 34 papers, talks and posts my Signal Engine had flagged on self-improving AI agents, and asked it to teach me how an agent gets better at its job without a new model.
I've answered 49 of its questions so far, and the lesson isn't finished. The first idea is the one this piece is about, and I got it wrong seven times in a row.
Seven wrong answers
The tutor kept giving me pairs of failures and asking which was which. In one run, the model works out 17 + 25 = 42, and the step that pulls out the final answer reports 17. In another, the model works out 17 + 25 = 32, and 32 is what gets reported. Both reports are wrong. They are different problems.
I kept lumping them together. Both reports are wrong, so both are the model's fault. Then I flipped it. There's software between the model and the report in both runs, so both had to be the software's fault. The tutor gave up on AI examples and tried clocks, ovens and broken vases, and I lumped the ovens and the vases together the same way. Then it asked me about a letter.
The author writes "meet at 6" and a clerk retypes it as "meet at 5". In a second letter the author writes "meet at 5", which is the wrong time, and the clerk types it faithfully. Which change fixes each one?
That one I got right. Fix the clerk in the first letter and the author in the second. Then I got the AI versions right too, because the question had changed. I'd been asking what kind of failure it was. The letter made me ask which change removes the error, and you can only answer that by putting two things side by side. What the author wrote against what the letter says. What the model said against what the report says, and before that, what the source held against what the model was handed. The fix goes where they first stop matching.
"But the AI is still wrong"
Once that landed I swung hard the other way. It's the objection I'd expect from anyone running AI in their business, so it's worth going slowly.
In the tutor's case, an agent writes that a paper reports 12%. The paper's abstract, stored where the agent could have checked it, says 47%. You change the setup so the report takes its number from the stored abstract instead of from the agent's sentence. Asked on its own, the model still says 12%.
Is the error fixed? I said no. Four answers running, at 70 to 90% confidence, I held that a wrong model output stays wrong until the model itself changes.
What turned it was mechanics. There are two places the number can come from. The stored abstract says 47% and the agent's sentence says 12%. The code that writes the report copies from one of them. Which number ends up in the report? Then the question I'd been refusing: is the report still wrong?
It is not. The model is still wrong, and nobody reads that sentence.
I picked the right answer to that one at 30% confidence. I accepted it before I believed it.
That is the case for looking at the setup first. What your customer sees is the report, not the model's private opinion. If the right fact already sits somewhere your system can reach, a change to the code around the model can fix what the customer sees, with the model you already pay for.
Only what can be copied
There is a hard edge to that. The setup can only copy a fact that already exists somewhere it can reach.
If a paper's author affiliation is on its arXiv page, the fix is to fetch the page and copy it across. If the digest is meant to say why the author wrote the paper, and that's written on no page anywhere, there is nothing to fetch. The only thing left to copy is the model's guess.
When it really is the model
Then there's the case where the setup has nothing left to give. The model had everything it needed, did every step it was meant to, and still produced something poor.
The tutor pulled the research on this, a paper from October called "Harness Evolution Hits a Ceiling: When Weight Training Should Begin". Its rule is to label each failure by the first thing that went wrong. Blocked tool calls, loops and running out of steps are process failures, and changing the setup fixes them. A plan that got delivered and is poor is a content failure, and that is what training the model is for.
The numbers back it, within limits. On a small 4-billion-parameter model, improving the setup alone took the share of unseen tasks that ended in a finished plan from 55% to 90%. On a 9-billion-parameter model, 97% of tasks already ended in a plan. The setup changes made those plans somewhat better, but a quarter of runs still ended in a poor plan, and by the end that was the biggest class of failure. These are small models on a travel-planning benchmark, so I read it as a rule with evidence behind it.
For anyone deciding whether to pay for a smarter model, that's the question. Did the model have what it needed and still get it wrong? Then it is the model. If it never saw the information, it is not.
Where the check breaks
Two papers my Signal Engine picked up say the split is messier than I've made it sound.
"When Agents Fail: Model or Harness, Who's to Blame?" tested four agent setups with four models, plus two models running in their makers' own setups for comparison, 52,168 runs in all. Which setup came out best changed from model to model, and some pairings finished their runs cleanly more often or less often than the model and the setup would predict on their own. It also cites an earlier study of failures that appeared only when a particular model met a particular setup. Comparing what the model said with what the report said will not always find one clean point where they part ways. Sometimes the answer is both.
"Your Policy Is Secretly a Harness" goes further. A model trained inside one setup picks up that setup's habits. In one test, reversing the order of the fields the model was shown, which changed nothing about the right answer, dropped a trained model's success from 85% to 19%. Keeping the model and changing the setup is not free either. A setup change can break habits the model was relying on.
So I treat the check's answer as the place to start looking.
Back to my digest
Run the check on my own pipeline and the model comes out clean. It was handed the first 500 characters of each item. The title and author list sat inside those 500, so about 300 characters of abstract were left. Its sentence described exactly that. The digest printed what the model wrote. So the break sat earlier, between the database and the step that writes the digest.
The cap has been in the code since July, and I did not know it existed. What changed is that a research step used to fetch the full text of the most relevant items, and since 21 October it has come back empty. It relies on a paid scraping service, and the month's 5,000 credits ran out. The step was built to keep going when it fails, so the digest still ships. It did, eight times in nine days, on about 300 characters an abstract. The model had been saying so in plain English since the 24th.
The digest step now gets the whole abstract for research papers, with the same model and the same prompts. It goes live with tomorrow morning's run, and the scraping credit tops up on 1 November. I'll know whether the entries start reporting results again when I read that digest, and I'll say so when I have.
The pattern in the wrong answers
Looking back, every wrong answer I gave on this idea had the same flaw. I picked a fix from something true of every case: there's software in the path, the output is wrong, the model is still wrong. Those are always true, so they cannot pick anything. Every time it clicked, I'd put two specific things side by side and found where they stopped matching. That's all "look systematically at what's coming from what" turns out to mean.
For one wrong output, I'd now ask to see four things. Where the right fact is kept, what the model was given, what it wrote, and what the report printed. If someone else runs the system, that is what I'd ask them for. If the report differs from what the model wrote, the fix is after the model. If the model was never given the fact, and the fact sits somewhere the system can reach, the fix is before it.
A wrong answer tells you something broke, not where.
The next piece in this notebook is what to do with that check once you're running it every week. That's how an agent gets better at its job without a new model.